import esda
import geopandas as gpd
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import seaborn as sns
import statsmodels.api as sm
from libpysal import graph
from sklearn import metrics
from spml import linear_model, searchRegression and geography
When trying to determine the effect of some (independent) variables on the outcome of phenomena (dependent variable), you often use regression to model such an outcome and understand the influence each of the variables has in the model. With spatial regression, it is the same. You just need to use the spatial dimension in a mindful way.
This session provides an introduction to ways of incorporating space into regression models, from spatial variables in standard linear regression to geographically weighted regression.
Data
You will work with the same data you already used in the session on spatial autocorrelation - the results of the second round of the presidential elections in Czechia in 2023, between Petr Pavel and Andrej Babiš, on a level of municipalities. You can read the election data directly from the original location.
elections = gpd.read_file(
"https://martinfleischmann.net/sds/autocorrelation/data/cz_elections_2023.gpkg"
)
elections = elections.set_index("name")
elections.head()| nationalCode | PetrPavel | AndrejBabis | sourceOfName | geometry | |
|---|---|---|---|---|---|
| name | |||||
| Želechovice nad Dřevnicí | 500011 | 61.73 | 38.26 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-518835.63 -1170505.52, -51790... |
| Petrov nad Desnou | 500020 | 49.07 | 50.92 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-559207.18 -1075123.25, -55624... |
| Libhošť | 500046 | 47.78 | 52.21 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-486502.29 -1123694.06, -48717... |
| Krhová | 500062 | 58.79 | 41.20 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-494514.83 -1136457.23, -49539... |
| Poličná | 500071 | 58.20 | 41.79 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-499678.51 -1143457.52, -49799... |
NoteAlternative
Instead of reading the file directly off the web, it is possible to download it manually, store it on your computer, and read it locally. To do that, you can follow these steps:
- Download the file by right-clicking on this link and saving the file
- Place the file in the same folder as the notebook where you intend to read it
- Replace the code in the cell above with:
elections = gpd.read_file(
"cz_elections_2023.gpkg",
)The election results give you the dependent variable - you will look at the percentage of votes Petr Pavel, the winner, received. From the map of the results and the analysis you did when exploring spatial autocorrelation you already know that there are some significant spatial patterns. Let’s look whether these patterns correspond to the composition of education levels within each municipality.
You can use the data from the Czech Statistical Office reflecting the situation during the Census 2021. The original table has been preprocessed and is available as a CSV.
education = pd.read_csv(
"https://martinfleischmann.net/sds/regression/data/education.csv"
)
education.head()| uzemi_kod | without_education | undetermined | incomplete_primary_education | lower_secondary_and_secondary_education | further_education | post_maturita_studies | bachelors_degree | doctoral_degree | masters_degree | higher_vocational_education | higher_vocational_education_in_a_conservatory | primary_education | complete_secondary_vocational_education | complete_secondary_general_education | okres | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 500011 | 0.570704 | 3.741281 | 1.141408 | 34.242232 | 1.775523 | 0.507292 | 2.853519 | 0.634115 | 12.935954 | 1.395054 | 0.126823 | 11.350666 | 17.945466 | 10.779962 | Zlín |
| 1 | 500020 | 0.885827 | 3.346457 | 1.968504 | 40.157480 | 2.066929 | 0.885827 | 1.771654 | 0.492126 | 6.299213 | 1.574803 | 0.000000 | 15.059055 | 16.338583 | 9.153543 | Šumperk |
| 2 | 500046 | 0.359195 | 3.232759 | 0.790230 | 39.152299 | 2.514368 | 0.790230 | 3.520115 | 0.215517 | 10.632184 | 1.364943 | 0.143678 | 9.770115 | 15.301724 | 12.212644 | Nový Jičín |
| 3 | 500062 | 0.238237 | 3.573556 | 1.072067 | 32.757594 | 2.084574 | 1.131626 | 3.037522 | 0.178678 | 13.281715 | 0.714711 | 0.119119 | 11.316260 | 18.701608 | 11.792734 | Vsetín |
| 4 | 500071 | 0.412939 | 2.890571 | 1.238816 | 34.067447 | 1.720578 | 0.757054 | 3.028217 | 0.137646 | 11.080523 | 0.894701 | 0.000000 | 9.772884 | 20.027529 | 13.971094 | Vsetín |
NoteAlternative
Instead of reading the file directly off the web, it is possible to download it manually, store it on your computer, and read it locally. To do that, you can follow these steps:
- Download the file by right-clicking on this link and saving the file
- Place the file in the same folder as the notebook where you intend to read it
- Replace the code in the cell above with:
education = pd.read_csv(
"education.csv",
)The first thing you need to do is to merge the two tables, to have both dependent and independent variables together. The municipality code in the elections table is in the "nationalCode" column, while in the education table in the "uzemi_kod" column.
elections_data = elections.merge(education, left_on="nationalCode", right_on="uzemi_kod")
elections_data.head()| nationalCode | PetrPavel | AndrejBabis | sourceOfName | geometry | uzemi_kod | without_education | undetermined | incomplete_primary_education | lower_secondary_and_secondary_education | ... | post_maturita_studies | bachelors_degree | doctoral_degree | masters_degree | higher_vocational_education | higher_vocational_education_in_a_conservatory | primary_education | complete_secondary_vocational_education | complete_secondary_general_education | okres | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 500011 | 61.73 | 38.26 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-518835.63 -1170505.52, -51790... | 500011 | 0.570704 | 3.741281 | 1.141408 | 34.242232 | ... | 0.507292 | 2.853519 | 0.634115 | 12.935954 | 1.395054 | 0.126823 | 11.350666 | 17.945466 | 10.779962 | Zlín |
| 1 | 500020 | 49.07 | 50.92 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-559207.18 -1075123.25, -55624... | 500020 | 0.885827 | 3.346457 | 1.968504 | 40.157480 | ... | 0.885827 | 1.771654 | 0.492126 | 6.299213 | 1.574803 | 0.000000 | 15.059055 | 16.338583 | 9.153543 | Šumperk |
| 2 | 500046 | 47.78 | 52.21 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-486502.29 -1123694.06, -48717... | 500046 | 0.359195 | 3.232759 | 0.790230 | 39.152299 | ... | 0.790230 | 3.520115 | 0.215517 | 10.632184 | 1.364943 | 0.143678 | 9.770115 | 15.301724 | 12.212644 | Nový Jičín |
| 3 | 500062 | 58.79 | 41.20 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-494514.83 -1136457.23, -49539... | 500062 | 0.238237 | 3.573556 | 1.072067 | 32.757594 | ... | 1.131626 | 3.037522 | 0.178678 | 13.281715 | 0.714711 | 0.119119 | 11.316260 | 18.701608 | 11.792734 | Vsetín |
| 4 | 500071 | 58.20 | 41.79 | Český úřad zeměměřický a katastrální | MULTIPOLYGON (((-499678.51 -1143457.52, -49799... | 500071 | 0.412939 | 2.890571 | 1.238816 | 34.067447 | ... | 0.757054 | 3.028217 | 0.137646 | 11.080523 | 0.894701 | 0.000000 | 9.772884 | 20.027529 | 13.971094 | Vsetín |
5 rows × 21 columns
That is all sorted and ready to be used in a regression.
Non-spatial linear regression
Before jumping into spatial regression, let’s start with the standard linear regression. A useful start is to explore the data using an ordinary least squares (OLS) linear regression model.
OLS model
While this course is not formula-heavy, in this case, it is useful to use the formula to explain the logic of the algorithm. The OLS tries to model the dependent variable \(y\) as the linear combination of independent variables \(x_1, x_2, ... x_n\):
\[y_{i}=\alpha+\beta _{1}\ x_{i1}+\beta _{2}\ x_{i2}+\cdots +\beta _{p}\ x_{ip}+\varepsilon _{i}\]
where \(\epsilon_{i}\) represents unobserved random variables and \(\alpha\) represents an intercept - a constant. You know the \(y_i\), all of the \(x_i\) and try to estimate the coefficients. In Python, you can run linear regression using implementations from more than one package (e.g., statsmodels, scikit-learn, spreg). This course covers statsmodels approach as it offers additional insights over scikit-learn.
First, you need to define independent variables. That is equal to education data without a few of the columns that represent other data.
independent = education.drop(columns=["uzemi_kod", "okres"])
independent.head(3)| without_education | undetermined | incomplete_primary_education | lower_secondary_and_secondary_education | further_education | post_maturita_studies | bachelors_degree | doctoral_degree | masters_degree | higher_vocational_education | higher_vocational_education_in_a_conservatory | primary_education | complete_secondary_vocational_education | complete_secondary_general_education | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 0.570704 | 3.741281 | 1.141408 | 34.242232 | 1.775523 | 0.507292 | 2.853519 | 0.634115 | 12.935954 | 1.395054 | 0.126823 | 11.350666 | 17.945466 | 10.779962 |
| 1 | 0.885827 | 3.346457 | 1.968504 | 40.157480 | 2.066929 | 0.885827 | 1.771654 | 0.492126 | 6.299213 | 1.574803 | 0.000000 | 15.059055 | 16.338583 | 9.153543 |
| 2 | 0.359195 | 3.232759 | 0.790230 | 39.152299 | 2.514368 | 0.790230 | 3.520115 | 0.215517 | 10.632184 | 1.364943 | 0.143678 | 9.770115 | 15.301724 | 12.212644 |
statsmodels (above imported as sm) offers an intuitive API to define the linear regression. In our case, we also need to include an intercept, by adding a constant. We also need to avoid perfect multi-collinearity as our education variables sum up to one.
X = sm.add_constant(independent.drop(columns='without_education'))
X.head(3)| const | undetermined | incomplete_primary_education | lower_secondary_and_secondary_education | further_education | post_maturita_studies | bachelors_degree | doctoral_degree | masters_degree | higher_vocational_education | higher_vocational_education_in_a_conservatory | primary_education | complete_secondary_vocational_education | complete_secondary_general_education | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 1.0 | 3.741281 | 1.141408 | 34.242232 | 1.775523 | 0.507292 | 2.853519 | 0.634115 | 12.935954 | 1.395054 | 0.126823 | 11.350666 | 17.945466 | 10.779962 |
| 1 | 1.0 | 3.346457 | 1.968504 | 40.157480 | 2.066929 | 0.885827 | 1.771654 | 0.492126 | 6.299213 | 1.574803 | 0.000000 | 15.059055 | 16.338583 | 9.153543 |
| 2 | 1.0 | 3.232759 | 0.790230 | 39.152299 | 2.514368 | 0.790230 | 3.520115 | 0.215517 | 10.632184 | 1.364943 | 0.143678 | 9.770115 | 15.301724 | 12.212644 |
With the data ready, you can fit the model and estimate all betas and \(\varepsilon\).
ols = sm.OLS(elections_data["PetrPavel"], X).fit()The ols object offers a handy summary() function providing most of the results from the fitting in one place.
ols.summary()| Dep. Variable: | PetrPavel | R-squared: | 0.423 |
|---|---|---|---|
| Model: | OLS | Adj. R-squared: | 0.422 |
| Method: | Least Squares | F-statistic: | 352.6 |
| Date: | Thu, 29 Oct 2026 | Prob (F-statistic): | 0.00 |
| Time: | 10:11:55 | Log-Likelihood: | -22397. |
| No. Observations: | 6254 | AIC: | 4.482e+04 |
| Df Residuals: | 6240 | BIC: | 4.492e+04 |
| Df Model: | 13 | ||
| Covariance Type: | nonrobust |
| coef | std err | t | P>|t| | [0.025 | 0.975] | |
|---|---|---|---|---|---|---|
| const | 36.3411 | 9.252 | 3.928 | 0.000 | 18.204 | 54.478 |
| undetermined | -0.1742 | 0.104 | -1.676 | 0.094 | -0.378 | 0.030 |
| incomplete_primary_education | -0.4502 | 0.171 | -2.632 | 0.009 | -0.786 | -0.115 |
| lower_secondary_and_secondary_education | -0.0731 | 0.093 | -0.786 | 0.432 | -0.255 | 0.109 |
| further_education | 0.6043 | 0.147 | 4.114 | 0.000 | 0.316 | 0.892 |
| post_maturita_studies | 0.9906 | 0.223 | 4.433 | 0.000 | 0.553 | 1.429 |
| bachelors_degree | 0.8013 | 0.131 | 6.124 | 0.000 | 0.545 | 1.058 |
| doctoral_degree | 0.8602 | 0.237 | 3.624 | 0.000 | 0.395 | 1.325 |
| masters_degree | 0.7610 | 0.099 | 7.699 | 0.000 | 0.567 | 0.955 |
| higher_vocational_education | 1.3691 | 0.160 | 8.539 | 0.000 | 1.055 | 1.683 |
| higher_vocational_education_in_a_conservatory | 2.4042 | 0.584 | 4.117 | 0.000 | 1.260 | 3.549 |
| primary_education | -0.2899 | 0.101 | -2.878 | 0.004 | -0.487 | -0.092 |
| complete_secondary_vocational_education | 0.5061 | 0.097 | 5.197 | 0.000 | 0.315 | 0.697 |
| complete_secondary_general_education | 0.4500 | 0.100 | 4.485 | 0.000 | 0.253 | 0.647 |
| Omnibus: | 130.315 | Durbin-Watson: | 1.680 |
|---|---|---|---|
| Prob(Omnibus): | 0.000 | Jarque-Bera (JB): | 215.929 |
| Skew: | 0.189 | Prob(JB): | 1.29e-47 |
| Kurtosis: | 3.828 | Cond. No. | 3.88e+03 |
Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
[2] The condition number is large, 3.88e+03. This might indicate that there are
strong multicollinearity or other numerical problems.
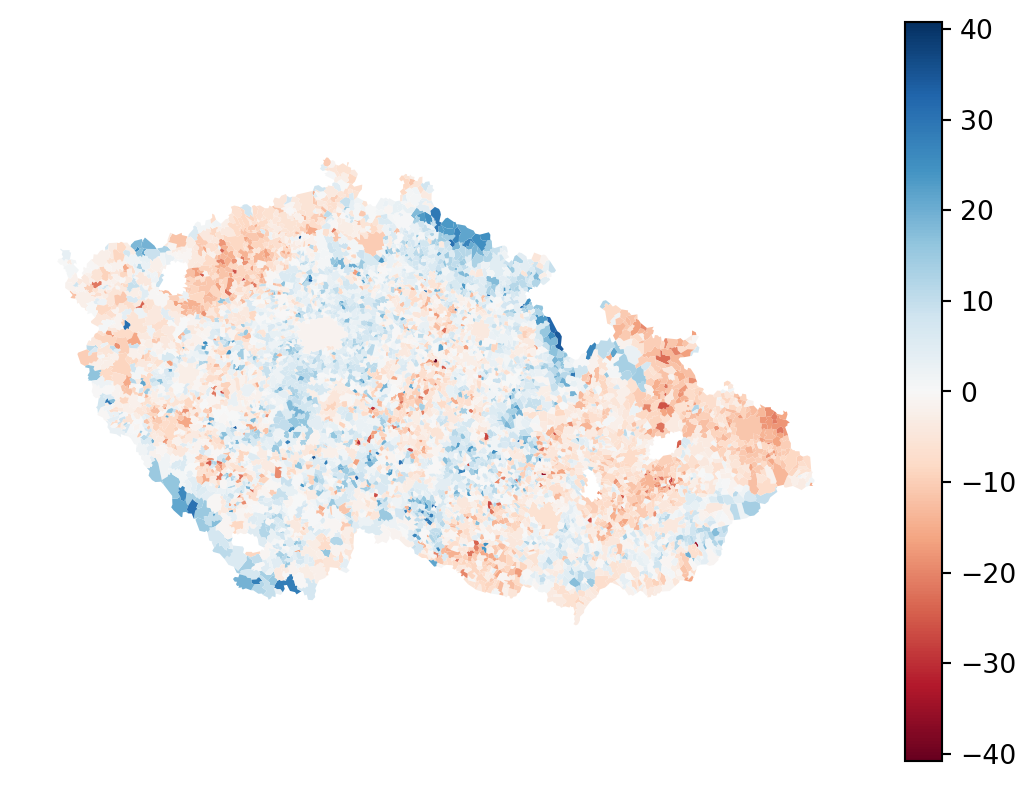
It is clear that education composition has a significant effect on the outcome of the elections but can explain only about 42% of its variance (adjusted \(R^2\) is 0.422). A higher amount of residents with only primary education tends to lower Pavel’s gain while a higher amount of university degrees tends to increase the number of votes he received. That is nothing unexpected. However, let’s make use of geography and unpack these results a bit.
Spatial heterogeneity
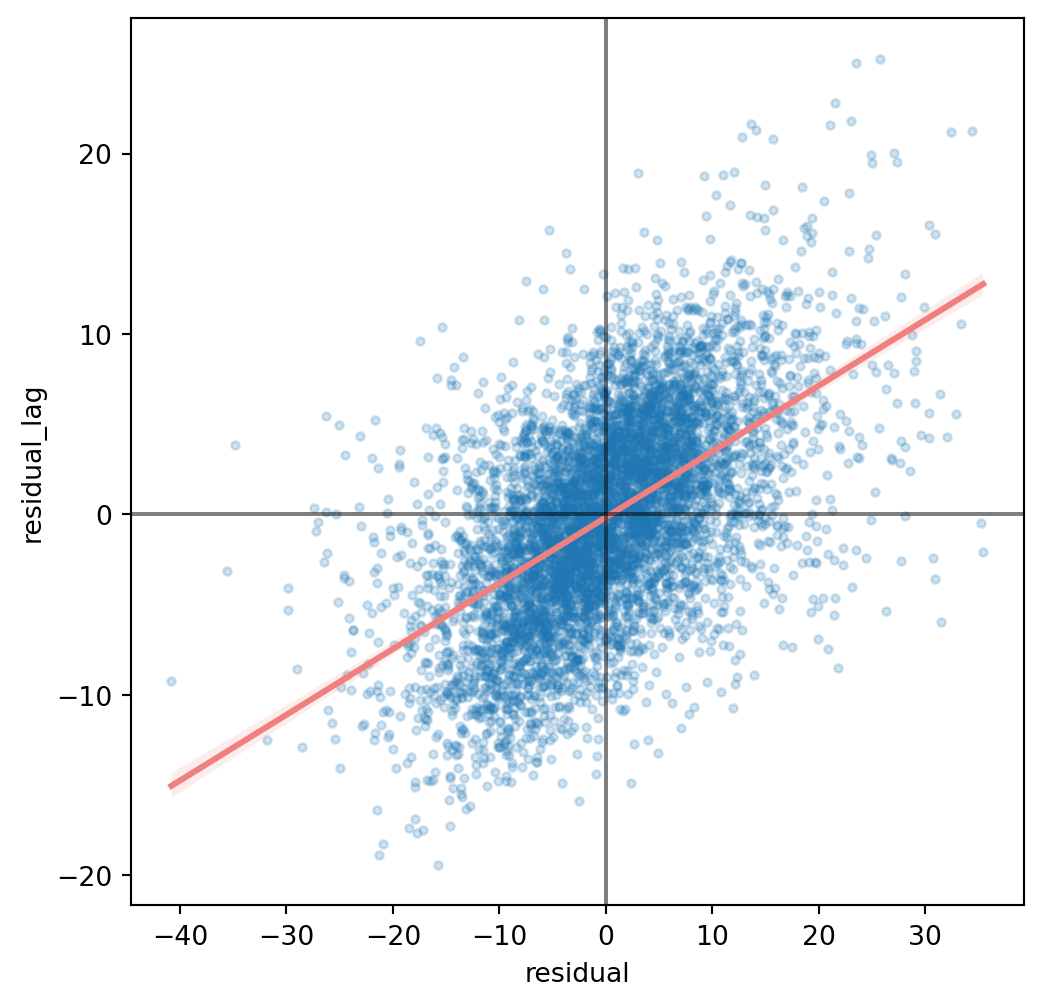
Not all areas behave equally, it seems that some systematically vote for Pavel more than for Babiš while others vote for him less. You need to account for this when building a regression model. One way is by capturing spatial heterogeneity. It implicitly assumes that the outcome of the model spatially varies. You can expect \(\alpha\) to vary across space, or individual values of \(\beta\). Spatial fixed effects capture the former.
Spatial fixed effects
You need to find a way to let \(\alpha\) change across space. One option is through the proxy variable capturing higher-level geography. You have information about okres (the closest translation to English would probably be district or county) each municipality belongs to. Let’s start by checking if that could be useful by visualising residuals within each. While you can use the box plot directly, it may be better to sort the values by median residuals, so let’s complicate the code a bit.
1medians = (
elections_data.groupby("okres")
.residual.median()
.to_frame("okres_residual")
)
f, ax = plt.subplots(figsize=(16, 6))
2sns.boxplot(
3 data=elections_data.merge(
medians, how="left", left_on="okres", right_index=True
4 ).sort_values("okres_residual"),
5 x="okres",
6 y="residual",
)
7_ = plt.xticks(rotation=90)- 1
-
Get median residual value per okres using
groupbyand convert the resultingSeriestoDataFrameto be able to merge it with the original data. - 2
- Create a box plot and pass the data.
- 3
-
The data is the
elections_datatable merged with themediansthat are after merge stored as the"okres_residual"column. - 4
-
Sort by the
"okres_residual"column. - 5
- The x value should represent each okres.
- 6
- The y value should represent residuals.
- 7
- Rotate x tick labels by 90 degrees for readability.
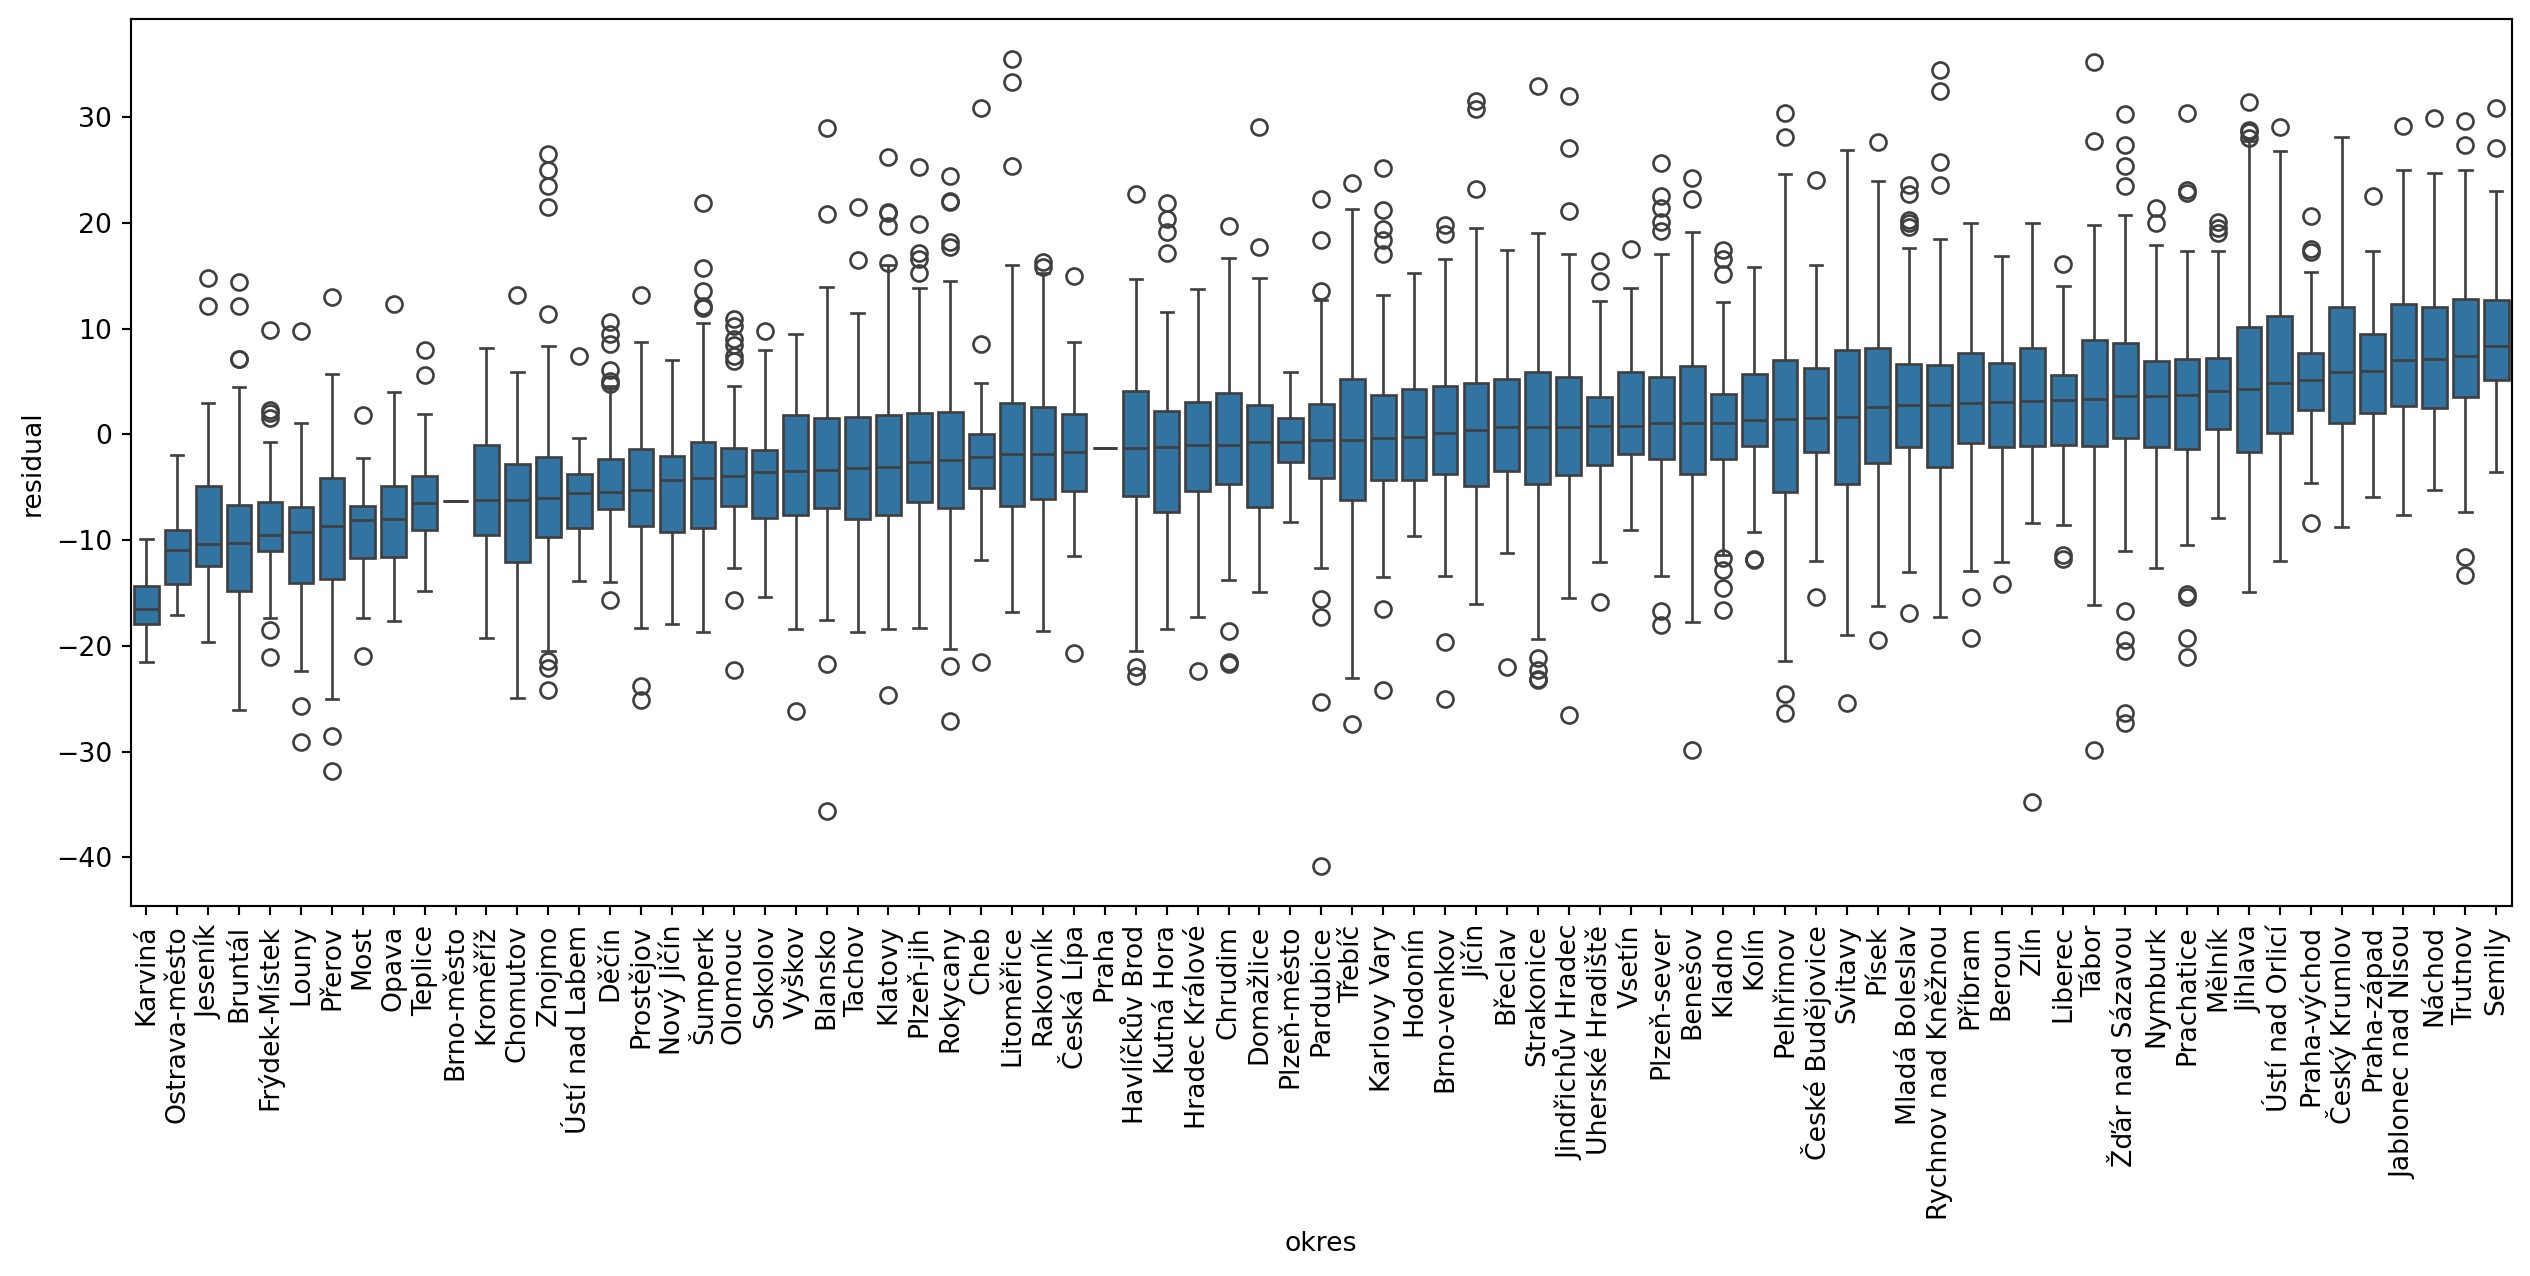
There are clear differences among these geographies, with a gradient between median -16.5 and 8.3. In a model that does not show spatial heterogeneity across higher-level geographies like these, all medians would be close to zero. This is positive information as it indicates, that we can encode these geographies in the model as a spatial proxy. Using statsmodels, you can adapt the equation and include "okres" as a dummy variable.
- 1
-
Create dummy variables from the
'okres'categories. Since you are now including a categorical variable okres, we don’t need an intecept as the dummy variable takes its role. By omitting the intercept, the coefficient can be directly interpreted as spatially varying \(\alpha\). - 2
- Join the dummies together with original data.
Fit the OLS model using the new data.
ols_fe = sm.OLS(elections_data["PetrPavel"], X).fit()Since every unique value in the "okres" column is now treated as a unique variable the summary is a bit longer than before.
ols_fe.summary()| Dep. Variable: | PetrPavel | R-squared: | 0.571 |
|---|---|---|---|
| Model: | OLS | Adj. R-squared: | 0.565 |
| Method: | Least Squares | F-statistic: | 92.21 |
| Date: | Thu, 29 Oct 2026 | Prob (F-statistic): | 0.00 |
| Time: | 10:12:09 | Log-Likelihood: | -21472. |
| No. Observations: | 6254 | AIC: | 4.312e+04 |
| Df Residuals: | 6164 | BIC: | 4.373e+04 |
| Df Model: | 89 | ||
| Covariance Type: | nonrobust |
| coef | std err | t | P>|t| | [0.025 | 0.975] | |
|---|---|---|---|---|---|---|
| undetermined | -0.2906 | 0.091 | -3.190 | 0.001 | -0.469 | -0.112 |
| incomplete_primary_education | -0.4534 | 0.150 | -3.024 | 0.003 | -0.747 | -0.159 |
| lower_secondary_and_secondary_education | -0.2363 | 0.082 | -2.895 | 0.004 | -0.396 | -0.076 |
| further_education | 0.2114 | 0.129 | 1.633 | 0.103 | -0.042 | 0.465 |
| post_maturita_studies | 0.5907 | 0.195 | 3.022 | 0.003 | 0.207 | 0.974 |
| bachelors_degree | 0.6961 | 0.115 | 6.030 | 0.000 | 0.470 | 0.922 |
| doctoral_degree | 0.2778 | 0.214 | 1.296 | 0.195 | -0.142 | 0.698 |
| masters_degree | 0.5969 | 0.088 | 6.815 | 0.000 | 0.425 | 0.769 |
| higher_vocational_education | 0.5115 | 0.144 | 3.559 | 0.000 | 0.230 | 0.793 |
| higher_vocational_education_in_a_conservatory | 2.0816 | 0.509 | 4.086 | 0.000 | 1.083 | 3.080 |
| primary_education | -0.2957 | 0.088 | -3.353 | 0.001 | -0.469 | -0.123 |
| complete_secondary_vocational_education | 0.3216 | 0.085 | 3.775 | 0.000 | 0.155 | 0.489 |
| complete_secondary_general_education | 0.2972 | 0.088 | 3.388 | 0.001 | 0.125 | 0.469 |
| Benešov | 53.5696 | 8.116 | 6.601 | 0.000 | 37.660 | 69.479 |
| Beroun | 55.3698 | 8.134 | 6.807 | 0.000 | 39.424 | 71.315 |
| Blansko | 49.9944 | 8.128 | 6.151 | 0.000 | 34.060 | 65.929 |
| Brno-město | 47.3371 | 11.082 | 4.271 | 0.000 | 25.612 | 69.063 |
| Brno-venkov | 52.9594 | 8.134 | 6.511 | 0.000 | 37.014 | 68.905 |
| Bruntál | 40.6139 | 8.153 | 4.981 | 0.000 | 24.631 | 56.597 |
| Břeclav | 52.2218 | 8.152 | 6.406 | 0.000 | 36.241 | 68.203 |
| Cheb | 48.3279 | 8.153 | 5.928 | 0.000 | 32.346 | 64.310 |
| Chomutov | 43.6733 | 8.147 | 5.361 | 0.000 | 27.702 | 59.645 |
| Chrudim | 51.5555 | 8.125 | 6.345 | 0.000 | 35.627 | 67.484 |
| Domažlice | 50.4746 | 8.143 | 6.198 | 0.000 | 34.511 | 66.439 |
| Děčín | 46.3265 | 8.129 | 5.699 | 0.000 | 30.392 | 62.261 |
| Frýdek-Místek | 43.4517 | 8.138 | 5.339 | 0.000 | 27.498 | 59.406 |
| Havlíčkův Brod | 51.3506 | 8.131 | 6.316 | 0.000 | 35.411 | 67.290 |
| Hodonín | 51.5484 | 8.154 | 6.322 | 0.000 | 35.564 | 67.533 |
| Hradec Králové | 50.9286 | 8.131 | 6.263 | 0.000 | 34.988 | 66.869 |
| Jablonec nad Nisou | 60.3230 | 8.199 | 7.357 | 0.000 | 44.250 | 76.396 |
| Jeseník | 43.4420 | 8.245 | 5.269 | 0.000 | 27.279 | 59.605 |
| Jihlava | 56.8454 | 8.136 | 6.987 | 0.000 | 40.896 | 72.795 |
| Jindřichův Hradec | 53.4276 | 8.138 | 6.566 | 0.000 | 37.475 | 69.380 |
| Jičín | 52.7536 | 8.132 | 6.488 | 0.000 | 36.813 | 68.694 |
| Karlovy Vary | 51.3711 | 8.146 | 6.306 | 0.000 | 35.401 | 67.341 |
| Karviná | 35.1644 | 8.297 | 4.238 | 0.000 | 18.899 | 51.430 |
| Kladno | 52.9949 | 8.118 | 6.528 | 0.000 | 37.081 | 68.908 |
| Klatovy | 49.8094 | 8.127 | 6.129 | 0.000 | 33.878 | 65.741 |
| Kolín | 53.9306 | 8.128 | 6.635 | 0.000 | 37.997 | 69.864 |
| Kroměříž | 46.5417 | 8.143 | 5.716 | 0.000 | 30.579 | 62.504 |
| Kutná Hora | 50.4215 | 8.140 | 6.194 | 0.000 | 34.464 | 66.379 |
| Liberec | 53.7726 | 8.149 | 6.598 | 0.000 | 37.797 | 69.748 |
| Litoměřice | 50.3882 | 8.127 | 6.200 | 0.000 | 34.457 | 66.319 |
| Louny | 40.3466 | 8.127 | 4.964 | 0.000 | 24.414 | 56.279 |
| Mladá Boleslav | 55.5238 | 8.125 | 6.833 | 0.000 | 39.595 | 71.452 |
| Most | 41.7373 | 8.187 | 5.098 | 0.000 | 25.689 | 57.786 |
| Mělník | 56.1074 | 8.150 | 6.885 | 0.000 | 40.131 | 72.083 |
| Nový Jičín | 46.8763 | 8.161 | 5.744 | 0.000 | 30.879 | 62.874 |
| Nymburk | 54.9258 | 8.134 | 6.752 | 0.000 | 38.980 | 70.872 |
| Náchod | 59.7234 | 8.153 | 7.325 | 0.000 | 43.741 | 75.706 |
| Olomouc | 48.2054 | 8.126 | 5.933 | 0.000 | 32.276 | 64.135 |
| Opava | 43.8226 | 8.130 | 5.390 | 0.000 | 27.884 | 59.761 |
| Ostrava-město | 41.4334 | 8.368 | 4.951 | 0.000 | 25.029 | 57.838 |
| Pardubice | 51.5341 | 8.128 | 6.340 | 0.000 | 35.601 | 67.467 |
| Pelhřimov | 53.3010 | 8.118 | 6.566 | 0.000 | 37.387 | 69.215 |
| Plzeň-jih | 49.7863 | 8.135 | 6.120 | 0.000 | 33.840 | 65.733 |
| Plzeň-město | 52.2555 | 8.341 | 6.265 | 0.000 | 35.905 | 68.606 |
| Plzeň-sever | 53.4009 | 8.145 | 6.556 | 0.000 | 37.433 | 69.368 |
| Prachatice | 54.5449 | 8.149 | 6.694 | 0.000 | 38.570 | 70.519 |
| Praha | 52.5884 | 11.084 | 4.744 | 0.000 | 30.859 | 74.317 |
| Praha-východ | 58.3993 | 8.136 | 7.178 | 0.000 | 42.450 | 74.349 |
| Praha-západ | 59.0494 | 8.154 | 7.241 | 0.000 | 43.064 | 75.035 |
| Prostějov | 46.8490 | 8.124 | 5.767 | 0.000 | 30.924 | 62.774 |
| Písek | 54.7765 | 8.105 | 6.758 | 0.000 | 38.888 | 70.666 |
| Přerov | 42.5145 | 8.116 | 5.239 | 0.000 | 26.605 | 58.424 |
| Příbram | 55.5710 | 8.119 | 6.844 | 0.000 | 39.655 | 71.487 |
| Rakovník | 50.0472 | 8.131 | 6.155 | 0.000 | 34.109 | 65.986 |
| Rokycany | 50.5489 | 8.118 | 6.227 | 0.000 | 34.635 | 66.463 |
| Rychnov nad Kněžnou | 55.6241 | 8.142 | 6.832 | 0.000 | 39.663 | 71.585 |
| Semily | 61.9484 | 8.161 | 7.591 | 0.000 | 45.951 | 77.946 |
| Sokolov | 46.6443 | 8.174 | 5.707 | 0.000 | 30.621 | 62.668 |
| Strakonice | 52.0574 | 8.113 | 6.417 | 0.000 | 36.154 | 67.961 |
| Svitavy | 54.0551 | 8.132 | 6.647 | 0.000 | 38.113 | 69.997 |
| Tachov | 47.4973 | 8.131 | 5.841 | 0.000 | 31.557 | 63.437 |
| Teplice | 44.9451 | 8.187 | 5.490 | 0.000 | 28.895 | 60.995 |
| Trutnov | 59.9216 | 8.155 | 7.348 | 0.000 | 43.936 | 75.907 |
| Tábor | 56.0326 | 8.136 | 6.887 | 0.000 | 40.084 | 71.981 |
| Třebíč | 51.1940 | 8.123 | 6.302 | 0.000 | 35.270 | 67.118 |
| Uherské Hradiště | 51.8289 | 8.155 | 6.355 | 0.000 | 35.842 | 67.816 |
| Vsetín | 53.7686 | 8.170 | 6.581 | 0.000 | 37.753 | 69.784 |
| Vyškov | 48.5024 | 8.158 | 5.946 | 0.000 | 32.510 | 64.495 |
| Zlín | 54.6929 | 8.151 | 6.710 | 0.000 | 38.714 | 70.672 |
| Znojmo | 45.5421 | 8.127 | 5.604 | 0.000 | 29.610 | 61.474 |
| Ústí nad Labem | 45.3819 | 8.242 | 5.506 | 0.000 | 29.225 | 61.539 |
| Ústí nad Orlicí | 57.9950 | 8.103 | 7.158 | 0.000 | 42.111 | 73.879 |
| Česká Lípa | 49.7879 | 8.146 | 6.112 | 0.000 | 33.820 | 65.756 |
| České Budějovice | 54.5617 | 8.139 | 6.704 | 0.000 | 38.607 | 70.516 |
| Český Krumlov | 57.8695 | 8.181 | 7.073 | 0.000 | 41.831 | 73.908 |
| Šumperk | 47.6096 | 8.144 | 5.846 | 0.000 | 31.645 | 63.575 |
| Žďár nad Sázavou | 56.2910 | 8.131 | 6.923 | 0.000 | 40.352 | 72.230 |
| Omnibus: | 286.683 | Durbin-Watson: | 1.981 |
|---|---|---|---|
| Prob(Omnibus): | 0.000 | Jarque-Bera (JB): | 766.532 |
| Skew: | 0.226 | Prob(JB): | 3.55e-167 |
| Kurtosis: | 4.655 | Cond. No. | 3.43e+04 |
Notes:
[1] Standard Errors assume that the covariance matrix of the errors is correctly specified.
[2] The condition number is large, 3.43e+04. This might indicate that there are
strong multicollinearity or other numerical problems.
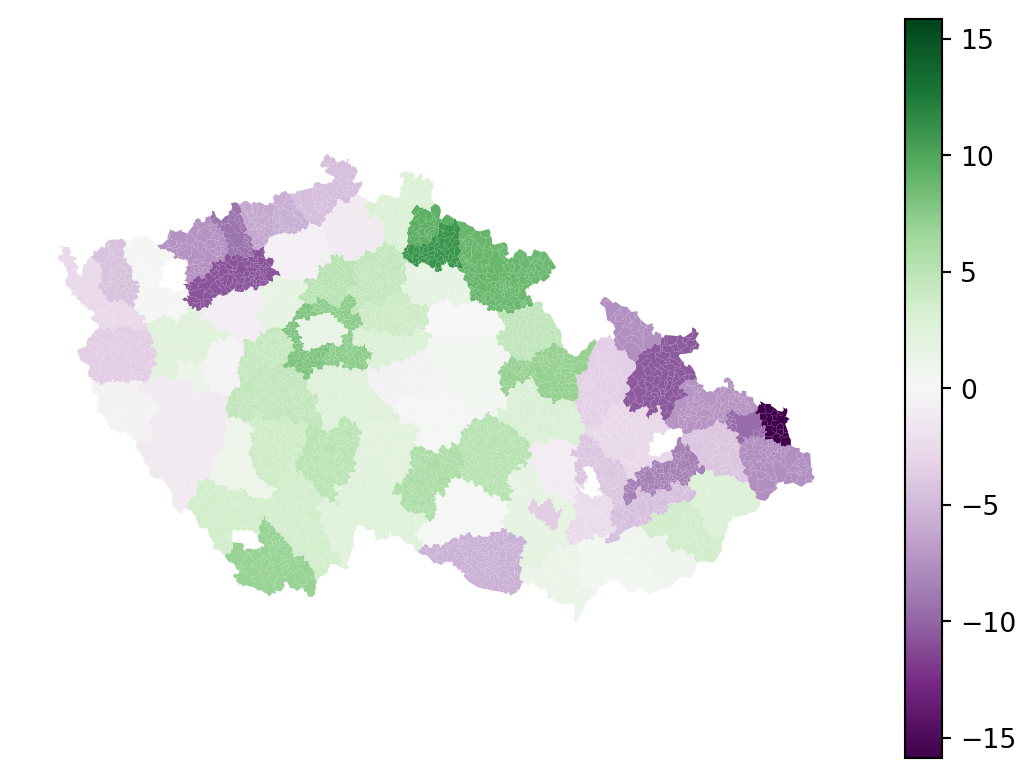
The coefficients for each of the values of the categorical variable "okres" are considered spatial fixed effects. They represent the starting point for the regression in that region. You can extract just those from the model by getting the .params Series and filtering it.
1fixed_effects = ols_fe.params["Benešov":]
fixed_effects.head()- 1
-
ols_fe.paramsis apandas.Seriesthat can be sliced.
Benešov 53.569563
Beroun 55.369844
Blansko 49.994365
Brno-město 47.337083
Brno-venkov 52.959431
dtype: float64The resulting Series can be merged with the elections_data, allowing us to map the spatial fixed effects.
- 1
-
Identify the maximum fixed effect value based on absolute value to specify
vminandvmaxvalues of the colormap. - 2
-
Merge the
fixed_effectstoelections_data. - 3
-
Merge requires a
DataFrame, so convert it to one with a column named"fixed_effect". - 4
-
Use the column
"okres"fromelections_dataas a merge key. - 5
-
Use the index of
fixed_effectsas a merge key. - 6
-
Use the left join, keeping the structure of
elections_dataintact. - 7
-
Plot the
"fixed_effect". - 8
-
Use
max_effectto specify the extent of the colormap to ensure it had mid-point at 0.
TipSpatial regimes and spatial dependence
Where spatial fixed effects allow \(\alpha\) to change geographically (within each okres), spatial regimes allow \(\beta_k\) to change within the same regions. Spatial regimes cannot be done within statsmodels as they require more specialised treatment offered by the spreg package. Check the Spatial regimes sections of theSpatial Regression chapter from the Geographic Data Science with Python by Rey et al. (2023) for more details.
The same chapter also covers the modelling of spatial dependence using spreg. Both are considered advanced usage within this course but feel free to read through the materials yourself.
With spatial fixed effects, you were able to include spatial dimension in the model through a proxy variable, resulting in an improvement of adjusted \(R^2\) from 0.422 to 0.565 while also extracting the fixed effect of each okres. However, the model is still global. We are not able to determine how explanatory is education composition regionally.
Geographically weighted regression
Geographically Weighted Regression (GWR) overcomes the limitation of the OLS, which provides a single global estimate by examining how the relationship between a dependent variable and independent variable changes across different geographic locations. It does this by moving a search window through the dataset, defining regions around each regression point, and fitting a regression model to the data within each region. This process is repeated for all the sample points in the dataset, resulting in localized estimates. These local estimates can then be mapped to visualize variations in variable relationships at different locations. However, for a dataset with 6254 observations, like the one used here, GWR will fit 6254 weighted regression models. That can eventually pose a limitation when dealing with larger datasets, for which fitting the GWR can take too long.
Visually, you can imagine a spatial kernel being constructed around each location (point, specifically) where the kernel function defines its shape and bandwidth its size, as illustrated in Figure 1.
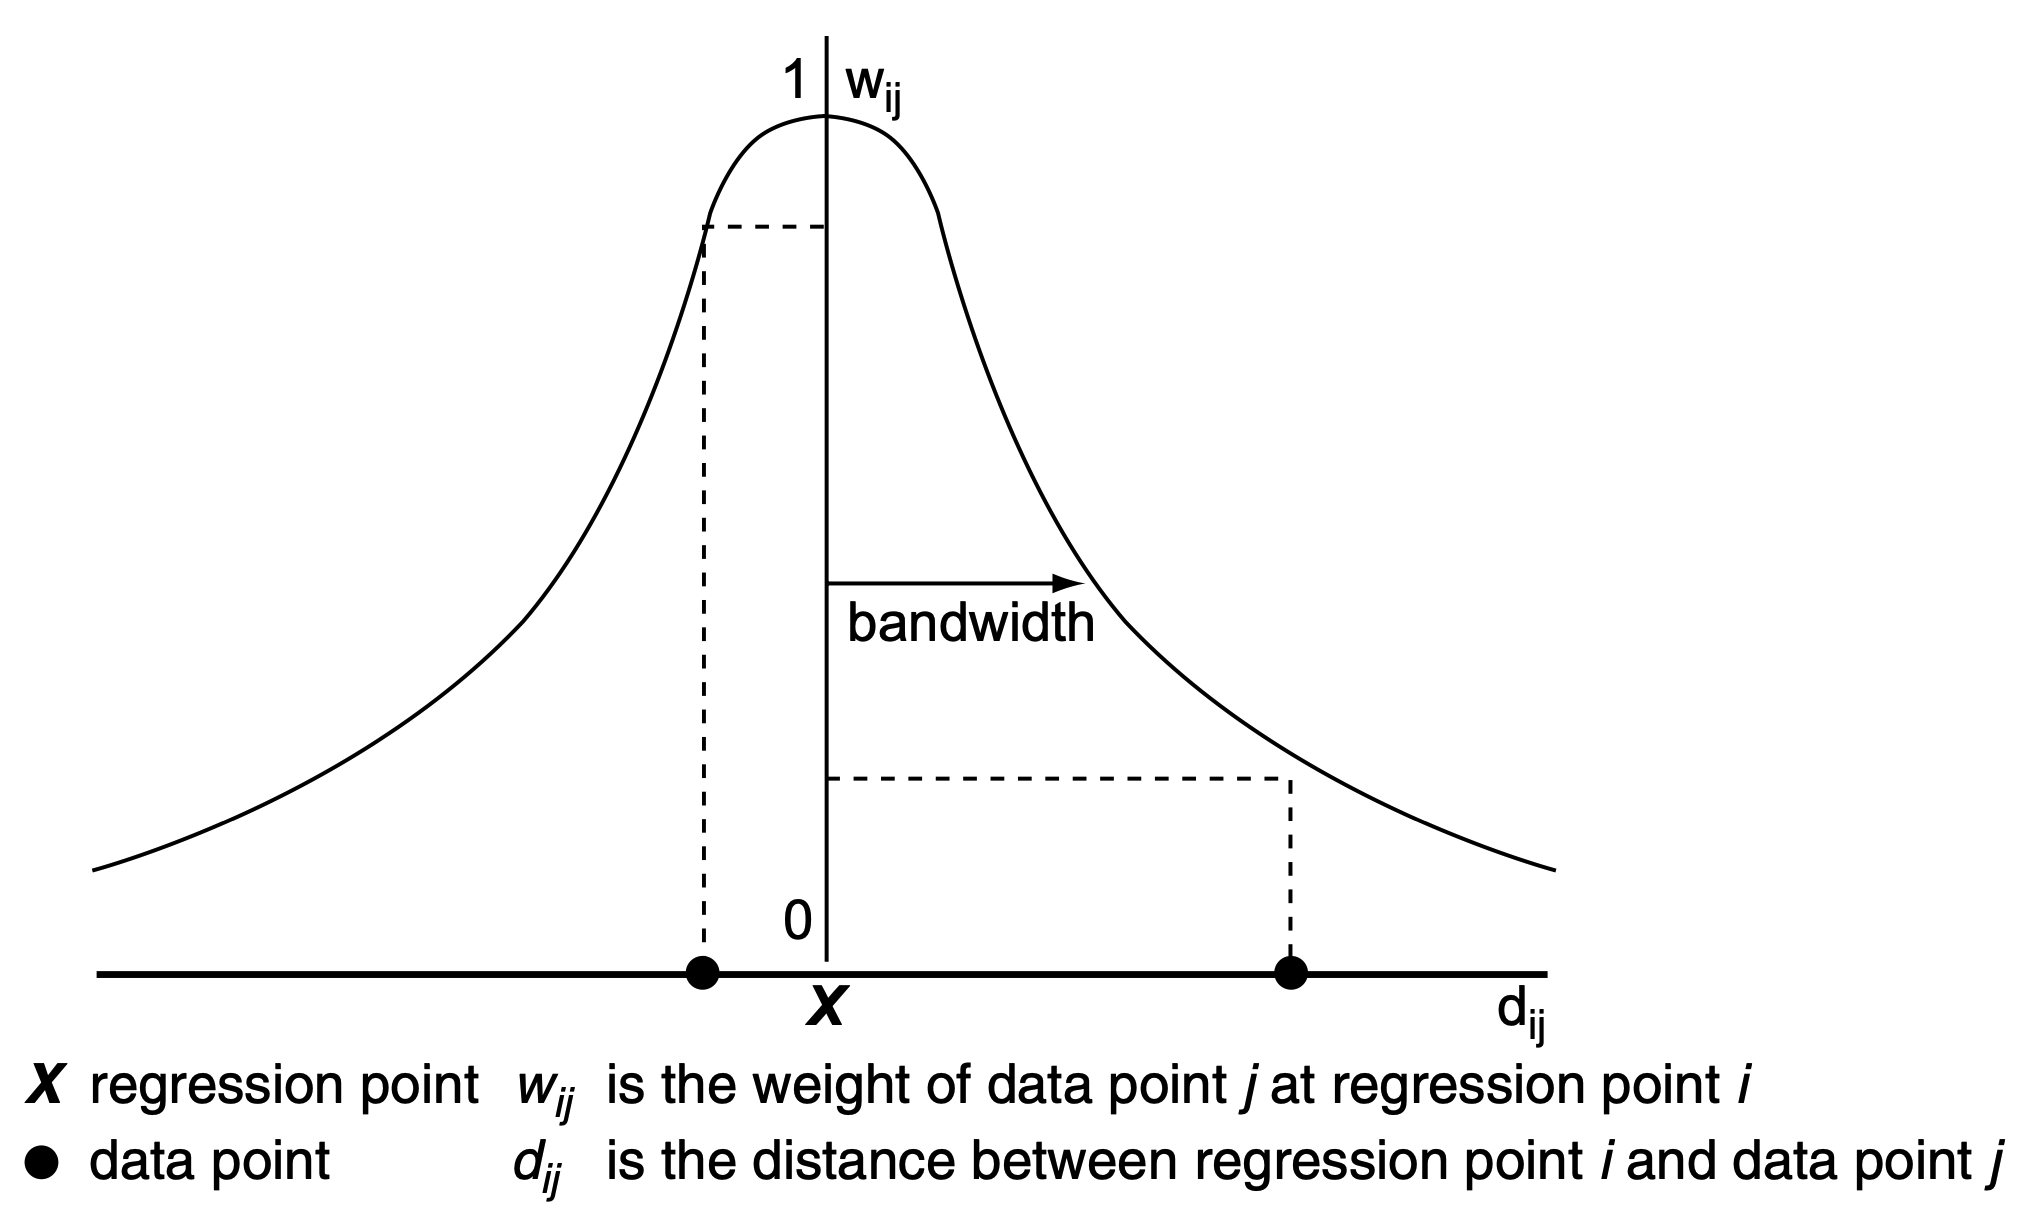
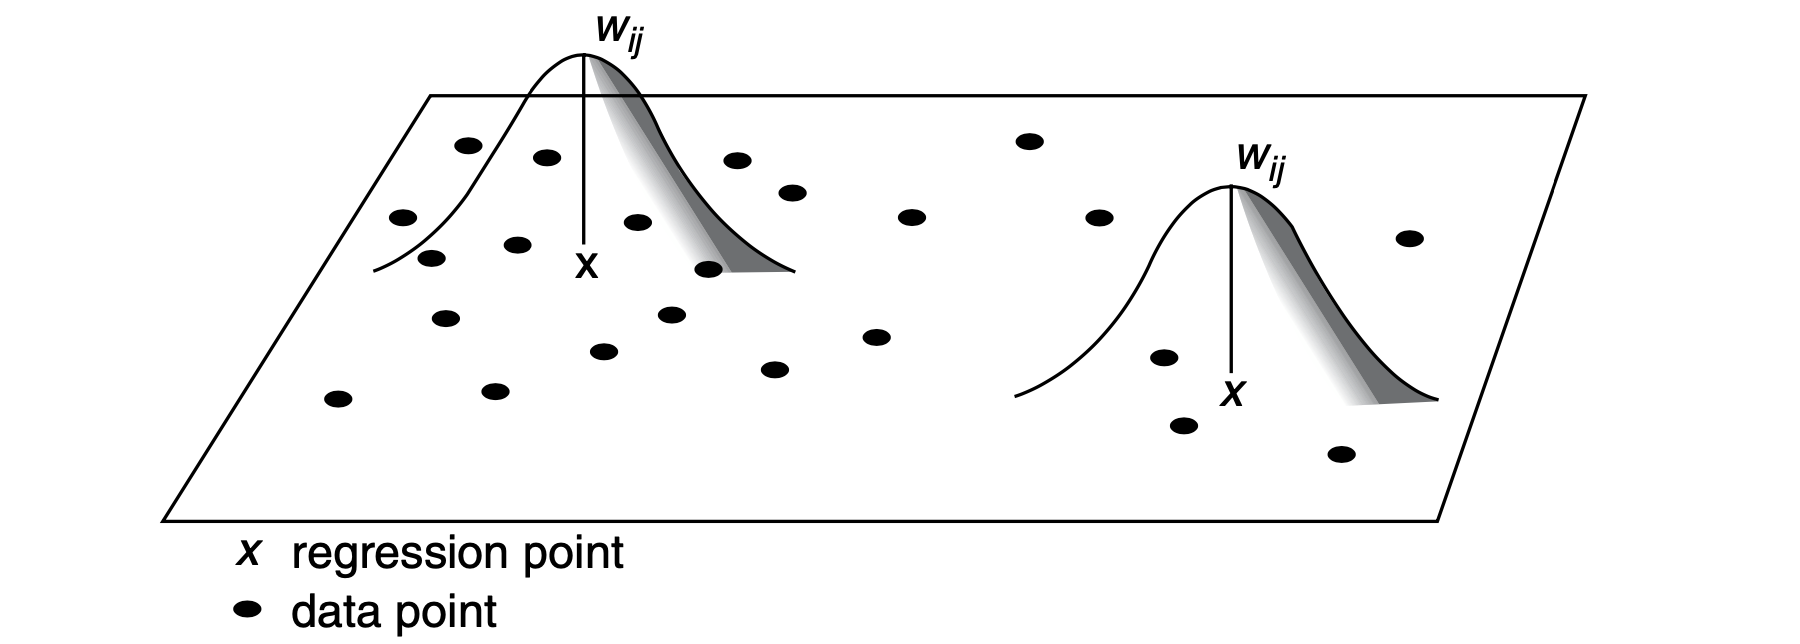
With kernels being the core of the GWR method, their specification significantly affects the resulting model. You can specify three parameters:
- Kernel shape: The shape of the curve formed by the kernel. In
spmlpackage used here, a range of kernels like"bisquare","gaussian", and"exponential"are supported. - Kernel size: The bandwidth distance specifying how large is the moving window.
- Bandwidth adaptivity: Bandwidth can be either fixed, specified by the metric distance, where the moving window is essentially formed as a buffer around a point, or adaptive, specified by the number of nearest neighbours.
The details of the implications of the choices are beyond the scope of this lesson but are discussed in-depth by Fotheringham et al. (2002).
Adaptive bandwidth
The method can be illustrated on a GWR using a adaptive bandwidth and the default bi-square kernel.
Bandwidth selection
You may have some theoretically defined bandwidth (e.g. you know that you want to consider only locations closer than 25 km) or use cross-validation to find the optimal bandwidth programmatically. CV can be an expensive procedure as the selection procedure fits models based on different bandwidths and compares residuals to choose the one where those are minimised. spml has the search.BandwidthSearch functionality that helps you with the search. This step may take some time (probably minutes).
- 1
- Define the model you intend to use.
- 2
- Pass in geometry to provide locations for observations. That is the only difference from the scikit-learn’s API we used above.
- 3
- Show the optimal bandwidth value.
np.int64(234)bandwidth.scores_.sort_index().plot()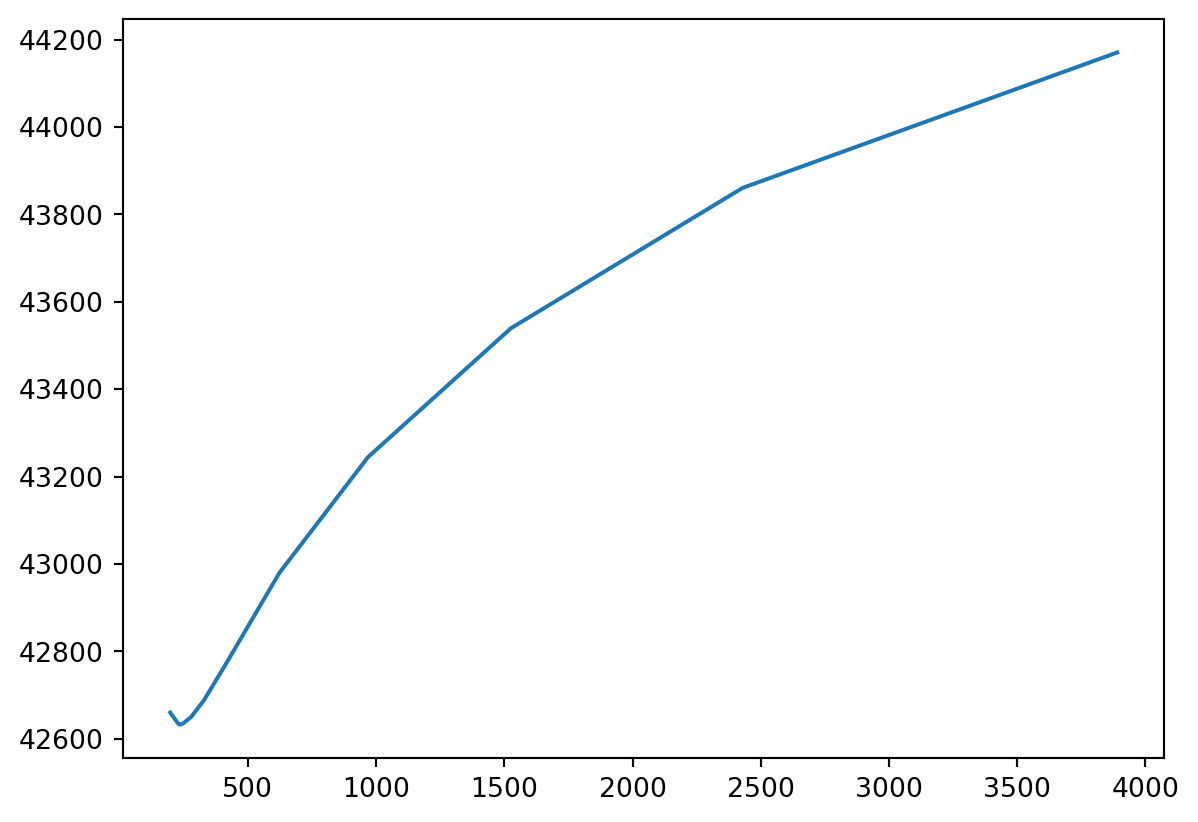
The optimal adaptive bandwidth seems to be 237 neighbors. You can pass it to the GWLinearRegression class and fit the regression.
gw_regression = linear_model.GWLinearRegression(
bandwidth=bandwidth.optimal_bandwidth_,
)
gw_regression.fit(
X=independent.drop(columns='without_education'),
y=elections_data["PetrPavel"],
geometry=elections_data.centroid,
)GWLinearRegression(bandwidth=np.int64(234))In a Jupyter environment, please rerun this cell to show the HTML representation or trust the notebook.
On GitHub, the HTML representation is unable to render, please try loading this page with nbviewer.org.
Parameters
| bandwidth | np.int64(234) | |
| fixed | False | |
| kernel | 'bisquare' | |
| include_focal | True | |
| graph | None | |
| n_jobs | -1 | |
| fit_global_model | True | |
| strict | False | |
| keep_models | False | |
| temp_folder | None | |
| batch_size | None | |
| coplanar | 'raise' | |
| verbose | False |
Fitted attributes
| Name | Type | Value |
|---|---|---|
| RSS_ | Series[float64](6254,) | focal 0 ...dtype: float64 |
| TSS_ | Series[float64](6254,) | 0 4957....dtype: float64 |
| aic_ | float64 | 4.231e+04 |
| aicc_ | float64 | 4.263e+04 |
| bic_ | float64 | 4.859e+04 |
| effective_df_ | float64 | 930.8 |
| feature_names_in_ | ndarray[object](13,) | ['undetermined','incomplete_primary_education', 'lower_secondary_and_secondary_education',...,'primary_education', 'complete_secondary_vocational_education', 'complete_secondary_general_education'] |
| hat_values_ | Series[float64](6254,) | 0 0.072...dtype: float64 |
| local_coef_ | DataFrame | undeter... x 13 columns] |
| local_intercept_ | Series[float64](6254,) | 0 65.14...dtype: float64 |
| local_r2_ | Series[float64](6254,) | 0 0.505...dtype: float64 |
| log_likelihood_ | float64 | -2.022e+04 |
| pred_ | Series[float64](6254,) | 0 57.45...dtype: float64 |
| resid_ | Series[float64](6254,) | 0 4.277...dtype: float64 |
| y_bar_ | Series[float64](6254,) | 0 56.39...dtype: float64 |
\(R^2\) is not computed automatically but can be measured using scikit-learn’s metrics module, which contains most of the other performance metrics we may be interested in. We need to provide the true value and the predicted one, which is available in the model.
metrics.r2_score(elections_data["PetrPavel"], gw_regression.pred_)0.7125346134809181The performance of the GWR based on the \(R^2\) is 0.71, another improvement over the fixed effects OLS model. It is probably as good as it can be given the data on education can explain only a part of the election behaviour.
Apart from the global \(R^2\), GWR can report \(R^2\) per geometry, giving us further insights into where education is the driver of the election result and where you need to look for other causes.
- 1
- Extract the array of local \(R^2\) and assign it as a column.
- 2
- Plot the values on a map. The theoretical minimum is 0 and the maximum is 1.

Higher local \(R^2\) means that the model is able to use the data at each municipality and its surrounding areas to provide a result that is closer to the actual observed gain of Petr Pavel.
You can use the new GWR model and compare its predicted results with the OLS done first and the actual results.
Code
f, axs = plt.subplots(3, 1, figsize=(7, 14))
elections_data.plot(
ols.predict(), legend=True, cmap="coolwarm", ax=axs[0]
)
elections_data.plot(
gw_regression.pred_, legend=True, cmap="coolwarm", vmin=0, vmax=100, ax=axs[1]
).set_axis_off()
elections_data.plot(
"PetrPavel", legend=True, cmap="coolwarm", vmin=0, vmax=100, ax=axs[2]
)
axs[0].set_title("OLS prediction")
axs[1].set_title("GWR prediction")
axs[2].set_title("Actual results")
axs[0].set_axis_off()
axs[1].set_axis_off()
axs[2].set_axis_off()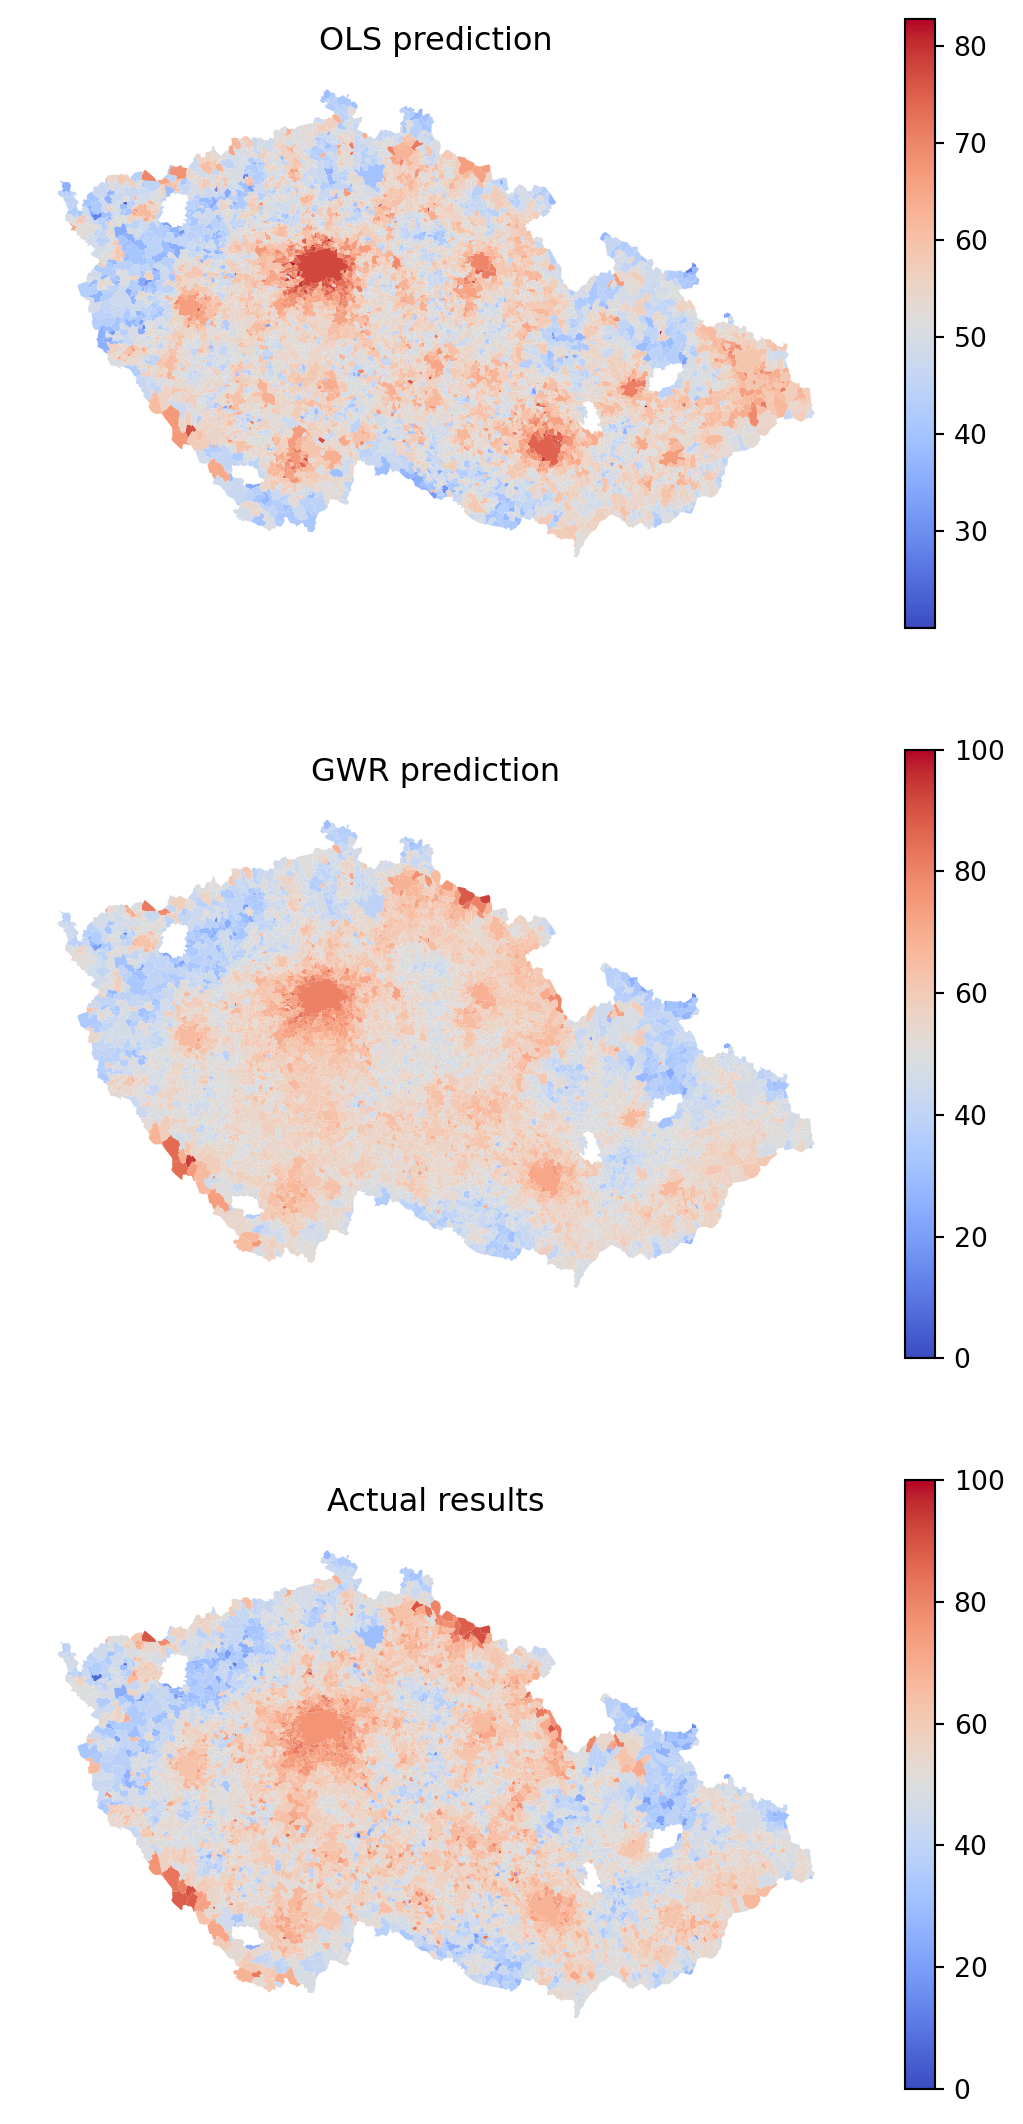
It is clear that the model is getting closer. Notice especially the mountains in the southwest and north of the country. You can check this even better by plotting residuals.
Code
f, axs = plt.subplots(2, 1, figsize=(7, 8))
elections_data.plot(
"residual",
legend=True,
cmap="RdBu",
vmin=-max_residual,
vmax=max_residual,
ax=axs[0],
)
elections_data.plot(
gw_regression.resid_,
legend=True,
cmap="RdBu",
vmin=-max_residual,
vmax=max_residual,
ax=axs[1],
)
axs[0].set_title("OLS residuals")
axs[1].set_title("GWR residuals")
axs[0].set_axis_off()
axs[1].set_axis_off()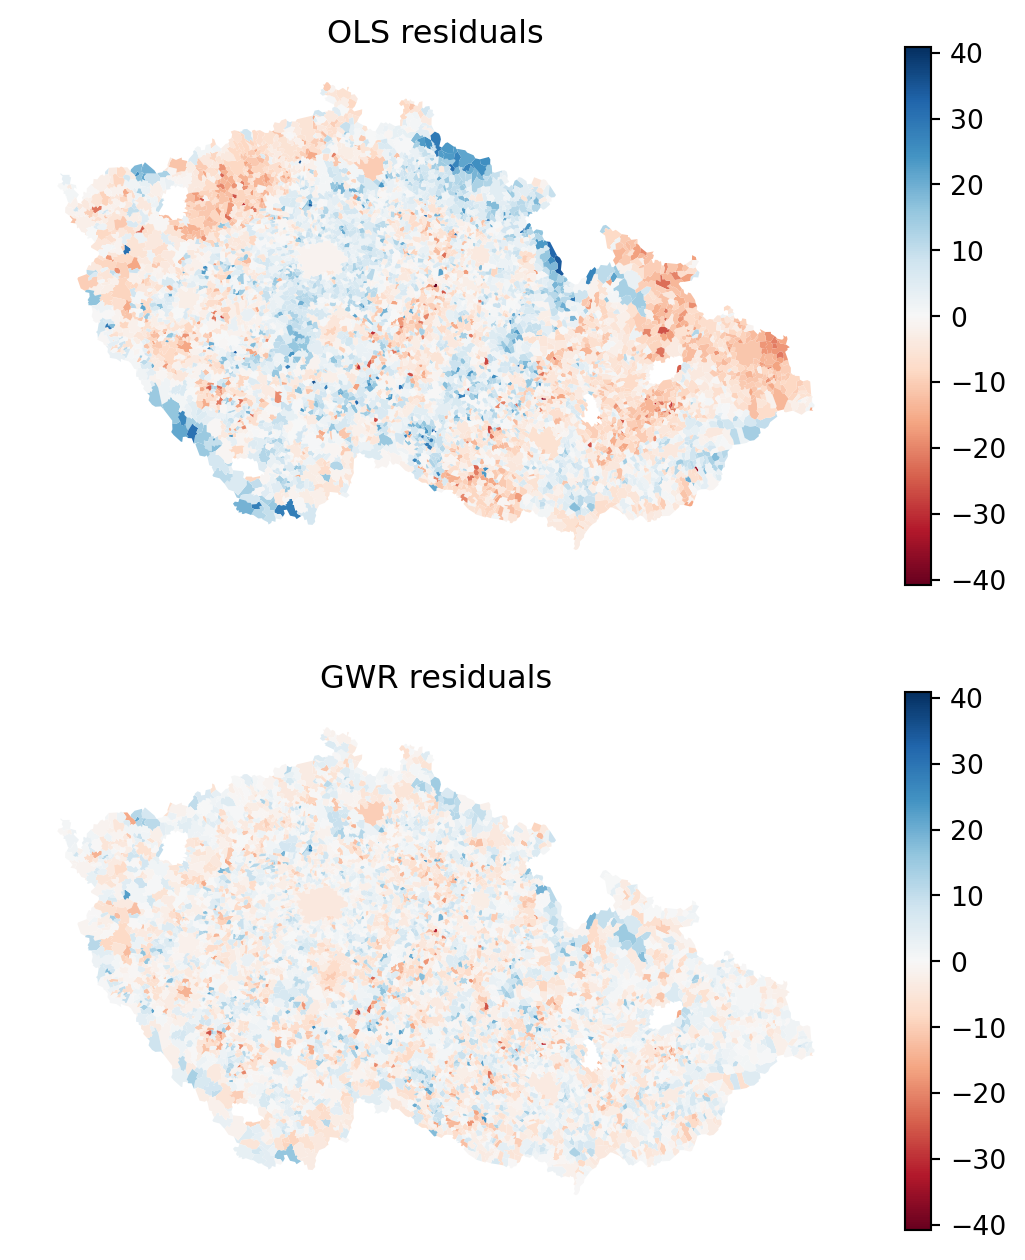
TipFixed bandwidth
If you’d like to use the fixed bandwidth, you can use same tools. Just specify fixed=True in both bandwidth selection and model fitting.
bandwidth = search.BandwidthSearch(
linear_model.GWLinearRegression,
fixed=True,
)gw_regression = linear_model.GWLinearRegression(
bandwidth=bandwidth.optimal_bandwidth_,
fixed=True,
)
TipAdditional reading
Have a look at the chapter Spatial Regression from the Geographic Data Science with Python by Rey et al. (2023) for more details and some other extensions.
If you’d like to learn the details of GWR, Geographically Weighted Regression by Fotheringham et al. (2002) is a good start.
Acknowledgements
References
Fotheringham, A Stewart, Chris Brunsdon, and Martin Charlton. 2002. Geographically Weighted Regression: The Analysis of Spatially Varying Relationships. John Wiley & Sons.
Rey, Sergio, Dani Arribas-Bel, and Levi John Wolf. 2023. Geographic Data Science with Python. Chapman & Hall/CRC Texts in Statistical Science. Taylor & Francis.
Rowe, Francisco, and Daniel Arribas-Bel. 2023. Spatial Modelling for Data Scientists. Https://smds-book.github.io/smds/.